Data Engineering
- 300+ Hours of training
- 450+ Hiring Partners
- Classroom & Live Online Training Available
- Hands-on training with assignments and capstone projects
- Next batch starts 10 Nov 2026 · Cohort Makalu
DedicatedPlacement Assistance
About the Data Engineering course
Learn to design and build the data pipelines that power analytics and machine learning teams at scale. The curriculum covers ETL and ELT processes, data warehousing concepts and modeling, and working with large-scale data infrastructure and orchestration tools. You'll practice building pipelines that are reliable, testable, and observable — not just scripts that work once — and come away understanding how raw, messy source data becomes the clean, trustworthy tables that dashboards and models depend on.
Learn From The Real Forward Deployed Engineers And AI Experts
Guest lectures and mentorship from Forward Deployed Engineers working at leading companies.
Companies Hiring In This Field
Companies that recruit for roles in this field.
 Amazon
Who Should Do The Data Engineering?
Who this program is built for.
- Working professionals looking to upskill or switch domains01
- M.Tech / M.E. graduates looking to specialize or pivot into a new tech track02
- B.Tech / B.E. graduates or final-year students in CS, IT, ECE, or related branches03
- BCA, MCA, or B.Sc / M.Sc (Computer Science, IT, or related) graduates04
- 05M.Com, B.Com, MBA, or BBA graduates
- 06Diploma holders in Computer Science, IT, or Engineering
- 07No prior coding experience required for beginner-track courses
- 08Final-year students and recent graduates from any stream
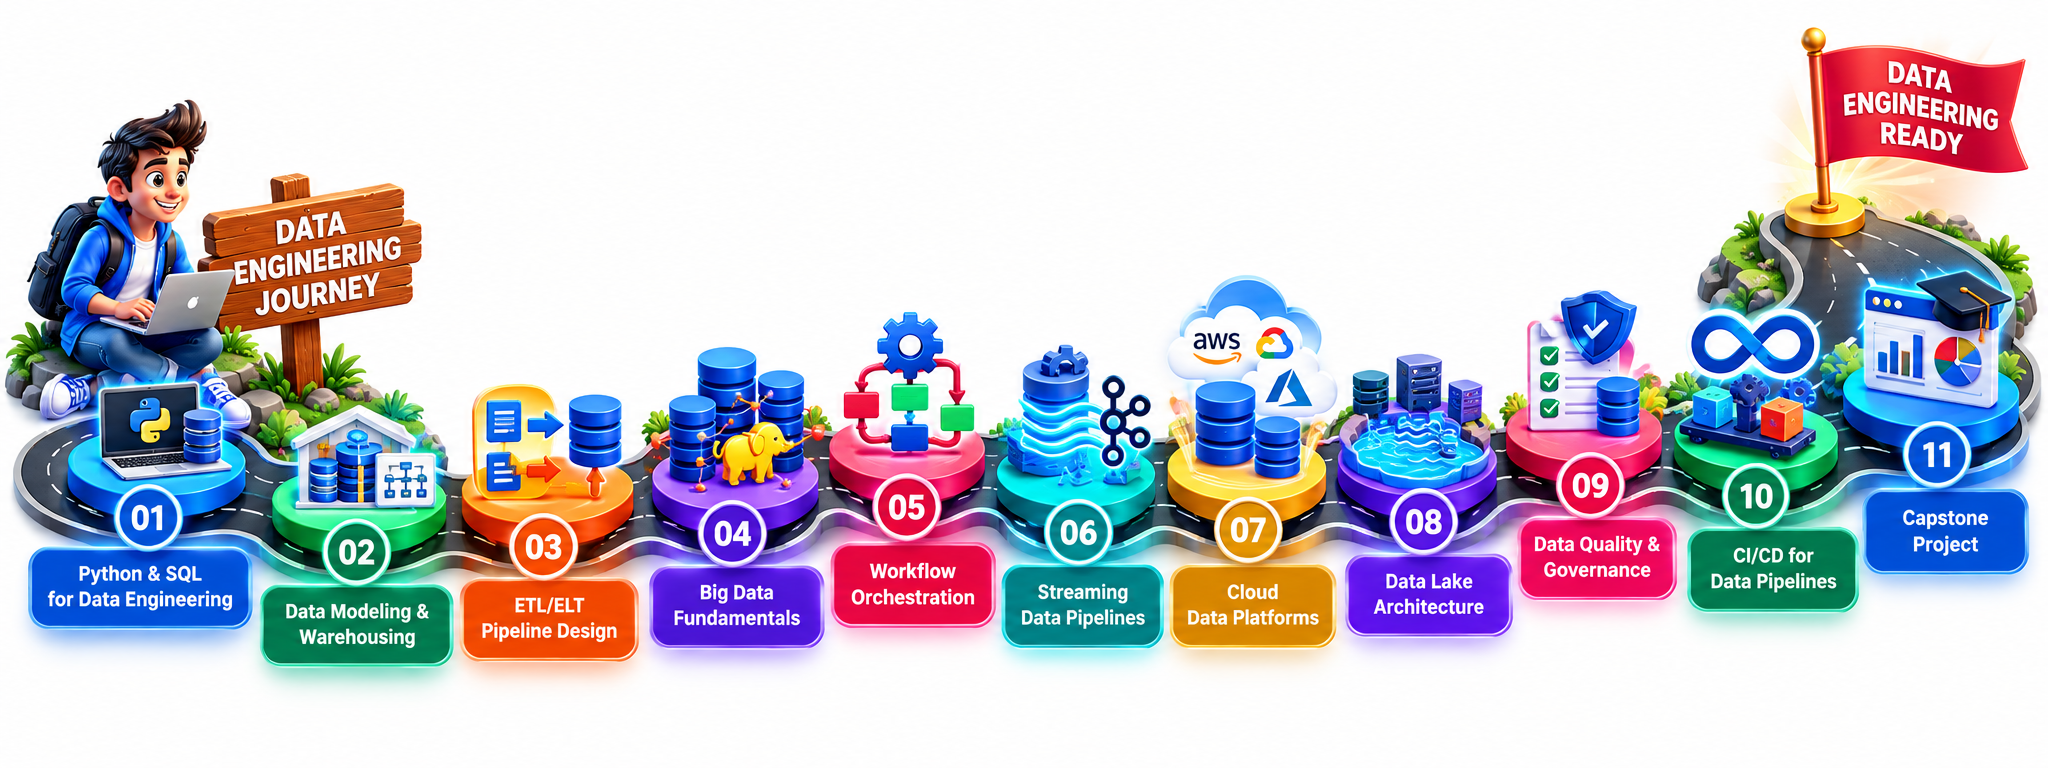
Data Engineering Learning Path
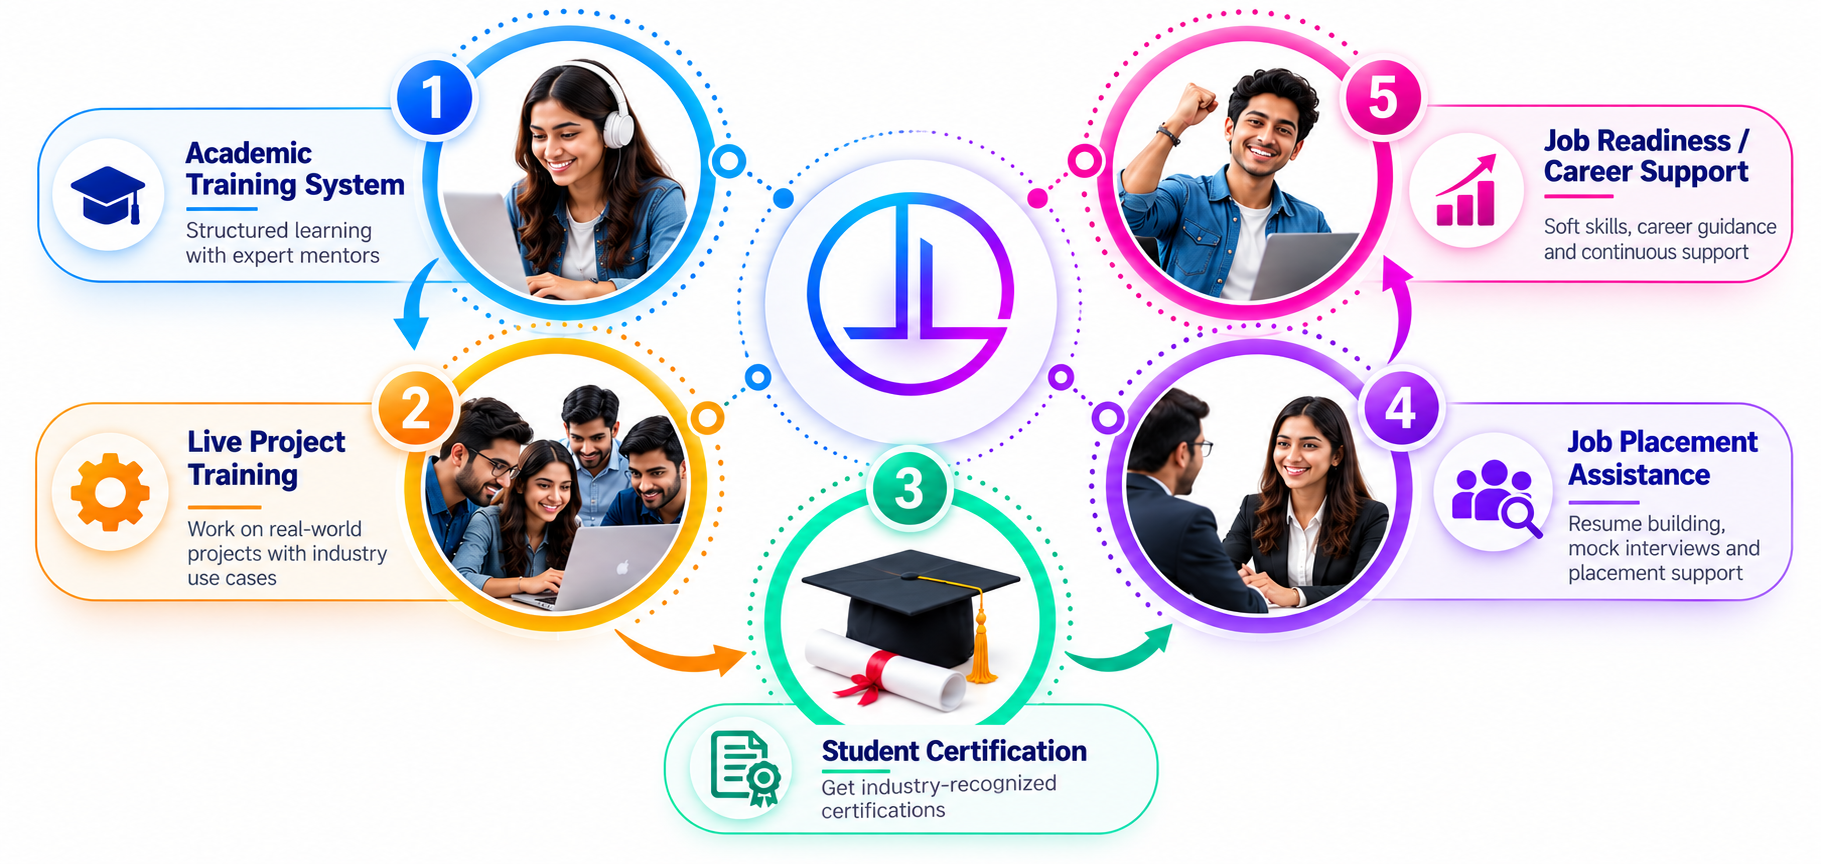
Learn → Build → Deploy → Solve Real Problems → Get Placed
Tech Stack
Technologies & Tools










Placement Path
From your first class to your first offer letter, here is how we take you there.
Career Opportunities with Data Engineering
Tap or hover a card to see what the role looks like day to day. Pay ranges are indicative market figures, not a guarantee of salary or placement.
ETL DeveloperIndicative market pay: ₹5 – 8 LPA
ETL Developer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Data EngineerIndicative market pay: ₹7 – 11 LPA
Data Engineer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Analytics EngineerIndicative market pay: ₹8 – 12 LPA
Analytics Engineer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Data Platform EngineerIndicative market pay: ₹9 – 14 LPA
Data Platform Engineer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Big Data EngineerIndicative market pay: ₹12 – 18 LPA
Big Data Engineer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Senior Data EngineerIndicative market pay: ₹14 – 20 LPA
Senior Data Engineer
A role you can aim for after Data Engineering. We help you prepare with projects, mock interviews and resume reviews.
Everything That You Get by Enrolling in Data Engineering
We've built this program with one goal — to guide, support, and uplift you at every stage of your career journey. From the first class to your first placement and beyond, every component has been created with your growth, confidence, and success in mind.
EMI Options Available
Placement Assistance
Collaborative Learning through Teamwork
Course Completion Certificate
Expert Career Guidance
Flexible Learning
ISO 9001:2015 Certified Institute
Hands on Project
Corporate-Ready Curriculum
Industry Expert Sessions
Internship programs
Mock Interview
Placement Mentorship
Resume Preparation Guidance
Recognised worldwide ISO
 IAF
 MSME
 DPIIT
Accreditation and Recognition from Top Industry Bodies
Our programs and certifications are affiliated with, and recognised by, globally respected standards and skill-development bodies.
Data Engineering Curriculum
Comprehensive modules designed to build Data Engineering skills step by step.
The core languages behind every data pipeline.
Key Topics
- Python for scripting and automation
- Advanced SQL for large datasets
- Working with structured and semi-structured data
Designing schemas that scale with the business.
Key Topics
- Star and snowflake schema design
- Normalization vs denormalization
- Data warehouse concepts (fact/dimension tables)
Moving and transforming data reliably at scale.
Key Topics
- Extract-transform-load vs extract-load-transform
- Building pipelines with Python
- Handling incremental loads and schema changes
Processing data too large for a single machine.
Key Topics
- Distributed computing concepts
- Hadoop ecosystem overview
- Processing data with Apache Spark
Automating and scheduling complex pipeline dependencies.
Key Topics
- DAGs and orchestration concepts
- Building pipelines with Apache Airflow
- Monitoring and alerting on pipeline failures
Working with data that arrives continuously, not in batches.
Key Topics
- Batch vs streaming architectures
- Apache Kafka fundamentals
- Building a simple streaming pipeline
Running data infrastructure on modern cloud platforms.
Key Topics
- Cloud storage and compute for data (S3, BigQuery, ADLS)
- Managed data pipeline services
- Cost and performance trade-offs in the cloud
Storing raw and processed data at any scale.
Key Topics
- Data lake vs data warehouse
- File formats: Parquet, Avro, ORC
- Lakehouse architecture concepts
Making sure the data people rely on is actually trustworthy.
Key Topics
- Data validation and testing frameworks
- Data lineage and cataloging
- Access control and data governance basics
Applying software engineering discipline to data pipelines.
Key Topics
- Version-controlling pipeline code
- Automated testing for pipelines
- Deploying pipeline changes safely
A complete, production-style data pipeline built end to end.
Key Topics
- Designing a pipeline for a real dataset
- Building ingestion, transformation, and storage layers
- Orchestrating, monitoring, and documenting the pipeline
The L&L AI Solutions Placement Mentorship Program
At L&L AI Solutions, we treat every learner as a professional in progress. Our Placement Mentorship Program pairs you with dedicated mentors who guide, support, and push you through every stage of your journey — from your first module to your final interview — so you leave not just trained, but genuinely ready to build a career in Data Engineering.
Stage 01
Sharpen Your Fundamentals & Interview Confidence
You'll work closely with mentors who pressure-test what you know and flag exactly where to focus next. Through regular check-ins, simulated interviews, and guided practice, you'll build the technical clarity and communication confidence to hold your own in any interview — technical or HR.
Skill Gap Assessments
Confidence Coaching
Technical Interview Simulations
Weekly Progress Scorecards
HR Round Simulations
Concept Refresher Sessions
Communication Skill Coaching
Key Support
Stage 02
Map Your Career Path & Build Your Professional Profile
Get complete clarity on how placements actually work — the roles open to you, what employers expect, and where you're the strongest fit. With a mentor by your side, you'll rebuild your resume and LinkedIn profile around the roles you're targeting, so your profile reads as capable as you actually are.
Career Path Walkthroughs
What to Expect from Placements
Resume Rebuild Support
LinkedIn Profile Makeover
Role Eligibility Reviews
Personal Branding Guidance
Extra Upskilling Support
Key Support
Stage 03
Apply, Interview & Land the Role
This is where preparation turns into real opportunity. Our placement team matches your profile to live openings, preps you for each specific interview, coordinates directly with employers, and stays with you — feedback and all — until an offer is in hand.
Live Job Opportunities
Profile-to-Role Matching
Role Briefings
Application Support
1:1 Interview Prep
Interview Scheduling Help
Post-Offer Support
Key Support
Data Engineering — FAQs
Everything you need to know about the course and admissions.
Classes are held live online and at our campus: 5th Floor, Draper Startup House Building, Rajiv Gandhi Nagar, Gachibowli, Hyderabad 500032.
Pipelines, warehousing, and infrastructure for data at scale.
Eligibility depends on your background. See the "Who Should Do The Data Engineering?" section on this page for the details.
The program runs for 6 Months.
The next cohort starts on 10 Nov 2026. Contact our admissions team to confirm seats and timings.
Yes. You receive a certificate of completion once you finish the program requirements.
Yes. We provide placement assistance, including mentorship, resume support and mock interviews. Placement assistance is not a guarantee of a job.
Yes. The course is built around hands-on practice and projects, ending with a capstone project you can add to your portfolio.
Yes. Mentors review your work and clear doubts throughout the program, not only during the capstone.
A laptop with a stable internet connection. Setup for the tools used is covered at the start of the course.
Our refund and cancellation terms are published on the Refund Policy page of this website. Please read them before you enrol, or ask our admissions team.